> For the complete documentation index, see [llms.txt](https://docs.ovaledge.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.ovaledge.com/release8.3/connectors/connector-repositories/data-warehouse/bigquery.md).

# BigQuery

This article outlines the integration with the BigQuery connector, enabling streamlined metadata management through features such as crawling, profiling, querying, data preview, and lineage building (both automatic and manual).

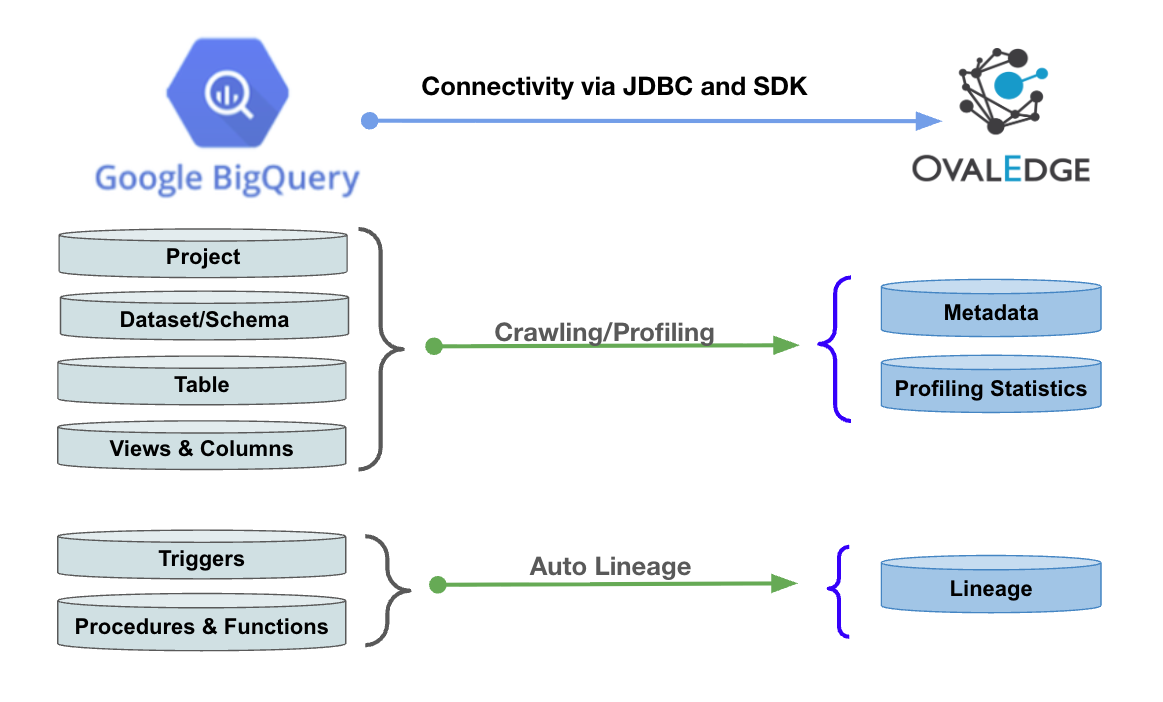
The connector establishes connectivity to **BigQuery** through **JDBC and SDK**. Authentication is configured using File Authentication or UI Authentication, with access established through a BigQuery service account and the required project, application, and authentication details.

<figure><img src="https://content.gitbook.com/content/8fgltewNgYZ8ucAp7Svt/blobs/vYnxdbZYL4yAT0TiTvR0/image.png" alt=""><figcaption></figcaption></figure>

## Overview

### Connector Details

<table data-header-hidden><thead><tr><th width="407.333251953125"></th><th></th></tr></thead><tbody><tr><td>Connector Category</td><td>Data Warehouse</td></tr><tr><td>OvalEdge Release Supported</td><td>Release6.3.4.x and later</td></tr><tr><td><p>Connectivity</p><p>[How the connection is established with BigQuery]</p></td><td>JDBC and SDK</td></tr></tbody></table>

### Connector Features

<table data-search="false"><thead><tr><th>Feature</th><th align="center">Availability</th></tr></thead><tbody><tr><td>Crawling</td><td align="center">✅</td></tr><tr><td>Delta Crawling</td><td align="center">❌</td></tr><tr><td>Profiling</td><td align="center">✅</td></tr><tr><td>Sample Profiling</td><td align="center">✅</td></tr><tr><td>Query Sheet</td><td align="center">✅</td></tr><tr><td>Data Preview</td><td align="center">✅</td></tr><tr><td>Auto Lineage</td><td align="center">✅</td></tr><tr><td>Manual Lineage</td><td align="center">✅</td></tr><tr><td>Secure Authentication via Credential Manager</td><td align="center">✅</td></tr><tr><td>Data Quality</td><td align="center">✅</td></tr><tr><td>DAM (Data Access Management)</td><td align="center">❌</td></tr><tr><td>Bridge</td><td align="center">✅</td></tr></tbody></table>

### Metadata Mapping

The following objects are crawled from BigQuery and mapped to the corresponding UI assets.

<table data-search="false"><thead><tr><th width="231.6666259765625">BigQuery Object</th><th width="198">BigQuery Attribute</th><th width="190.666748046875">OvalEdge Attribute</th><th width="181.3333740234375">OvalEdge Category</th><th width="170.666748046875">OvalEdge Type</th></tr></thead><tbody><tr><td>Project</td><td>Project</td><td>Database name</td><td>Database</td><td>Database</td></tr><tr><td>Dataset / Schema</td><td>Dataset Id / Schema Name</td><td>Schema name</td><td>Schemas</td><td>Schema</td></tr><tr><td>Table</td><td>Table Name</td><td>Table name</td><td>Tables</td><td>Table</td></tr><tr><td>Table</td><td>Table Type</td><td>Table Type</td><td>Tables</td><td>Table</td></tr><tr><td>Columns</td><td>column_name</td><td>Column name</td><td>Table Columns</td><td>Table Column</td></tr><tr><td>Columns</td><td>data_type</td><td>Column Type</td><td>Table Columns</td><td>Table Column</td></tr><tr><td>Views</td><td>Table_Name</td><td>View name</td><td>Views</td><td>Table</td></tr><tr><td>Views</td><td>View_Definition</td><td>Query</td><td>Views</td><td>Table</td></tr><tr><td>Routines (Procedures and Functions)</td><td>Routine_Name</td><td>Routine name</td><td>Procedures/ Functions</td><td>Code</td></tr><tr><td>Routines (Procedures and Functions)</td><td>Routine_Definition</td><td>Query</td><td>Procedures/ Functions</td><td>Code</td></tr><tr><td>Routines (Procedures and Functions)</td><td>Routine_Type</td><td>Job Type</td><td>Procedures/ Functions</td><td>Code</td></tr><tr><td>Routines (Procedures and Functions)</td><td>Created</td><td>Created date</td><td>Procedures/ Functions</td><td>Code</td></tr></tbody></table>

## Set up a Connection

### Prerequisites

The following are the prerequisites to establish a connection:

#### **Service Account User Permissions**

{% hint style="warning" %}
It is recommended to use a dedicated service account to establish the connection to the data source, configured with the following minimum set of permissions.
{% endhint %}

{% hint style="info" %}
**👨‍💻 Who can provide these permissions?** These permissions are typically granted by the BigQuery administrator, as users may not have the required access to assign them independently.
{% endhint %}

<table><thead><tr><th width="121.6666259765625">Objects</th><th width="166.6666259765625">Sys Tables</th><th width="286.333251953125">Role</th><th width="222.3333740234375">Access Permissions</th></tr></thead><tbody><tr><td>Schemas</td><td>INFORMATION_SCHEMA.SCHEMATA</td><td>roles/bigquery.dataViewer<br>roles/bigquery.metadataViewer<br>roles/bigquery.jobUser</td><td>bigquery.datasets.get</td></tr><tr><td>Tables</td><td>INFORMATION_SCHEMA.TABLES</td><td>roles/bigquery.dataViewer<br>roles/bigquery.metadataViewer<br>roles/bigquery.jobUser</td><td>bigquery.tables.get<br>bigquery.tables.list<br>bigquery.jobs.create</td></tr><tr><td>Columns</td><td>INFORMATION_SCHEMA.COLUMNS</td><td>roles/bigquery.dataViewer<br>roles/bigquery.metadataViewer<br>roles/bigquery.jobUser</td><td>bigquery.tables.get<br>bigquery.tables.list<br>bigquery.jobs.create</td></tr><tr><td>Views</td><td>INFORMATION_SCHEMA.VIEWS</td><td>roles/bigquery.dataViewer<br>roles/bigquery.metadataViewer<br>roles/bigquery.jobUser</td><td>bigquery.tables.get<br>bigquery.tables.list<br>bigquery.jobs.create</td></tr><tr><td>Routines (Procedures / Functions)</td><td>INFORMATION_SCHEMA.ROUTINES</td><td>roles/bigquery.dataViewer<br>roles/bigquery.metadataViewer<br>roles/bigquery.jobUser</td><td>bigquery.routines.get<br>bigquery.routines.list<br>bigquery.jobs.create</td></tr></tbody></table>

### Connection Configuration Steps

{% hint style="warning" %}
Users are required to have the Connector Creator role in order to configure a new connection.
{% endhint %}

1. Log into OvalEdge, go to **Administration** > **Connectors**, click **+ (New Connector),** search for **BigQuery**, and complete the required parameters.

{% hint style="info" %}
Fields marked with an asterisk (\*) are mandatory for establishing a connection.
{% endhint %}

<table><thead><tr><th width="219.3333740234375">Field Name</th><th>Description</th></tr></thead><tbody><tr><td>Connector Type</td><td>By default, "BigQuery" is displayed as the selected connector type.</td></tr><tr><td>Credential Manager*</td><td><p>Select the desired credential manager from the drop-down list. Relevant parameters will be displayed based on the selection.</p><p>Supported Credential Managers:</p><ul><li>OE Credential Manager</li><li>AWS Secrets Manager</li><li>HashiCorp Vault</li><li>Azure Key Vault</li></ul><p>For more details, click <a href="https://docs.ovaledge.com/release8.1/connectors/additional-requirements/credential-manager-configuration">here</a>.</p></td></tr><tr><td>Server*</td><td>By default, the BigQuery server URL (https://bigquery.googleapis.com) is pre-populated. If required, update the field with the BigQuery server endpoint or IP address (e.g., xxxx-xxxx.xxxx4ijtzasl.xx-south-1.rds.xxxxx.com or 1xx.xxx.1.x0).</td></tr><tr><td>License Add Ons</td><td><ul><li>Select the checkbox for the <strong>Auto Lineage</strong> Add-On to build data lineage automatically.</li><li>Select the checkbox for the <strong>Data Quality</strong> Add-On to identify data quality issues using data quality rules and anomaly detection.</li></ul><p>For more details, click <a href="https://docs.ovaledge.com/release8.1/connectors/introduction-to-connectors/setup-and-connectivity/license-types-and-add-ons">here</a>.</p></td></tr><tr><td>Connector Name*</td><td><p>Enter a unique name for the BigQuery connection              </p><p>(Example: "BigQuery_Prod").</p></td></tr><tr><td>Connector Environment</td><td>Select the environment (Example: PROD, STG) configured for the connector.<br>For more details, click <a href="https://docs.ovaledge.com/release8.1/connectors/introduction-to-connectors/setup-and-connectivity/prerequisites#connector-environment">here</a>.</td></tr><tr><td>Billing Project ID</td><td>Enter the Billing Project ID used for BigQuery query and data access billing.</td></tr><tr><td>Connector description</td><td>Enter a brief description of the connector.</td></tr><tr><td>Validation Type*</td><td><p>The following two types of validation are supported for BigQuery:</p><ul><li>File Authentication</li><li>UI Authentication</li></ul></td></tr></tbody></table>

{% tabs %}
{% tab title="File Authentication" %}

<table><thead><tr><th width="193.3333740234375">Field Name</th><th>Description</th></tr></thead><tbody><tr><td>Project Id*</td><td>Enter the Project ID associated with the BigQuery environment.</td></tr><tr><td>Application*</td><td>Enter the Application ID associated with the BigQuery environment and authorized for required operations.</td></tr><tr><td>File Path*</td><td>Enter the File Path of the BigQuery JSON file.</td></tr><tr><td>Regions (comma-separated)</td><td>Enter one or more BigQuery regions (e.g., US, EU, us-central1) - separate multiple regions with commas.</td></tr></tbody></table>
{% endtab %}

{% tab title="UI Authentication" %}

<table data-search="false"><thead><tr><th width="189.333251953125">Field Name</th><th>Description</th></tr></thead><tbody><tr><td>Account Type*</td><td>Enter the service account type used for BigQuery UI authentication.</td></tr><tr><td>Client id*</td><td>Enter the client ID associated with the BigQuery service account.</td></tr><tr><td>Client Email*</td><td>Enter the client email associated with the BigQuery service account.</td></tr><tr><td>Private Key*</td><td>Enter the private key for the BigQuery service account.</td></tr><tr><td>Private Key Id*</td><td>Enter the private key ID associated with the BigQuery service account.</td></tr><tr><td>Token Uri*</td><td>Enter the token Uri used for authentication with BigQuery.</td></tr><tr><td>Project Id*</td><td>Enter the Project ID associated with the BigQuery environment.</td></tr><tr><td>Application*</td><td>Enter the Application ID associated with the BigQuery environment and authorized for required operations.</td></tr><tr><td>Regions (comma-separated)</td><td>Enter one or more BigQuery regions (e.g., US, EU, us-central1) - separate multiple regions with commas.</td></tr></tbody></table>
{% endtab %}
{% endtabs %}

**Default Governance Roles**

<table data-header-hidden><thead><tr><th width="219.3333740234375"></th><th></th></tr></thead><tbody><tr><td>Default Governance Roles*</td><td>Select the appropriate users or teams for each governance role from the drop-down list. All users and teams configured in OvalEdge Security are displayed for selection.</td></tr></tbody></table>

**Admin Roles**

<table data-header-hidden><thead><tr><th width="219.3333740234375"></th><th></th></tr></thead><tbody><tr><td>Admin Roles*</td><td>Select one or more users from the dropdown list for Integration Admin and Security &#x26; Governance Admin. All users configured in OvalEdge Security are available for selection.</td></tr></tbody></table>

**No of Archive Objects**

<table data-header-hidden><thead><tr><th width="219.3333740234375"></th><th></th></tr></thead><tbody><tr><td>No Of Archive Objects*</td><td><p>This shows the number of recent metadata changes to a dataset at the source. By default, it is off. To enable it, toggle the Archive button and specify the number of objects to archive.</p><p>Example: Setting it to 4 retrieves the last four changes, displayed in the 'Version' column of the 'Metadata Changes' module.</p></td></tr></tbody></table>

**Bridge**

<table data-header-hidden><thead><tr><th width="219.3333740234375"></th><th></th></tr></thead><tbody><tr><td>Select Bridge*</td><td><p>If applicable, select the bridge from the drop-down list.</p><p>The drop-down list displays all active bridges configured in OvalEdge. These bridges enable communication between data sources and OvalEdge without altering firewall rules.</p></td></tr></tbody></table>

2. After entering all **connection details**, the following actions can be performed:
   1. Click **Validate** to verify the connection.
   2. Click **Save** to store the connection for future use.
   3. Click **Save & Configure** to apply additional settings before saving.
3. The saved connection will appear on the **Connectors home page.**

## Manage Connector Operations

### Crawl/Profile

{% hint style="warning" %}
To perform crawl and profile operations, users must be assigned the Integration Admin role.
{% endhint %}

The **Crawl/Profile** button allows users to select one or more **schemas** for **crawling** and **profiling**.

1. Navigate to the **Connectors page** and click **Crawl/Profile**.
2. Select the schemas to crawl.
3. The **Crawl** option is selected by default. Click the **Crawl & Profile** radio button to run both operations.
4. Click **Run** to collect metadata from the connected source and load it into the **OvalEdge Data Catalog**.
5. After a successful crawl, the information appears in the **Data Catalog > Databases** tab.

The **Schedule** checkbox allows automated **crawling** and **profiling** at defined intervals, from a minute to a year.

1. Click the **Schedule** checkbox to enable the **Select** Period drop-down.
2. Select a time period for the operation from the drop-down menu.
3. Click **Schedule** to initiate metadata collection from the connected source.
4. The system will automatically execute the selected operation (**Crawl** or **Crawl & Profile**) at the scheduled time.

#### Other Operations

The **Connectors** page in OvalEdge provides a centralized view of all configured connectors, including their health status.

**Managing connectors includes:**

* **Connector Health:** Displays the current status of each connector using a **green** icon for active connections and a **red** icon for inactive connections, helping to monitor connectivity with data sources.
* **Viewing**: Click the **Eye** icon next to the connector name to view connector details.

**Nine Dots Menu Options:**

To view, edit, validate, build lineage, configure, or delete connectors, click on the **Nine Dots** menu.

* **Edit Connector**: Update and revalidate the data source.
* **Validate Connector**: Check the connection's integrity.
* **Settings**: Modify connector settings.
  * **Crawler**: Configure data extraction.
  * **Profiler**: Customize data profiling rules and methods.
  * **Query Policies:** Define query execution rules based on roles.
  * **Access Instructions:** Add notes on how data can be accessed.
  * **Business Glossary Settings:** Manage term associations at the connector level.
  * **Anomaly Detection Settings:** Configure anomaly detection preferences at the connector level.
  * **Connection Pooling:** Configure database connection pool parameters to optimize database connectivity and resource utilization. For more details, click [here](https://docs.ovaledge.com/release8.2/connectors/introduction-to-connectors/setup-and-connectivity/connector-settings#connection-pooling).
  * **Lineage**: Select the parsing method (Regular or AI-Augmented) for generating lineage, and set a confidence threshold to control when AI-generated lineage is accepted or held for review. For more details, click [here](https://docs.ovaledge.com/release8.2/connectors/introduction-to-connectors/setup-and-connectivity/connector-settings#lineage-applicable-for-supported-connectors).
  * **Others**: Configure notification recipients for metadata changes.
* **Build Lineage**: Automatically build data lineage using source code parsing.
* **Delete Connector**: Remove a connector with confirmation.

For more details on connector settings, click [here](https://docs.ovaledge.com/release8.1/connectors/introduction-to-connectors/setup-and-connectivity/connector-settings).

## Data Types with Limited Support

The following data types are supported for crawling but have limited support across other connector features:

1. **GEOGRAPHY** – Profiling and querying are not supported.
2. **JSON** – Profiling and querying are not supported.
3. **STRUCT** – Profiling and querying are not supported.
4. **ENUM** – Crawling and profiling are not supported; Data View is supported.

## Troubleshooting

If incorrect parameters are entered, error messages may appear. Ensure all inputs are accurate to resolve these issues. If issues persist, contact the assigned support team.

{% tabs %}
{% tab title="Connectivity" %}

<table data-search="true"><thead><tr><th width="85">S.No.</th><th width="208.333251953125">Error Message(s)</th><th>Error Description &#x26; Resolution</th></tr></thead><tbody><tr><td>1</td><td>Error while validating connection: Error while validating BIGQUERY Connection : IOException block 1: Use JsonReader.setLenient(true) to accept malformed JSON at line 1 column 2 path</td><td><p>The system is unable to authenticate because the JSON key file path is incorrect, the file is missing, or the file is not in a valid JSON format.</p><p><strong>Resolution</strong>:</p><ul><li>Verify the file path in the connection settings and ensure the file is a valid JSON service account key.</li><li>Confirm the JSON file is a valid, unprotected service account key file and not encrypted or password-secured.</li><li>If connecting through a bridge, confirm that the JSON file exists on the bridge client machine and is accessible.</li></ul></td></tr><tr><td>2</td><td>Invalid details in Application or Project Id</td><td><p>Connection to BigQuery failed due to an incorrect Project ID or Application ID, or the dataset associated with the Application ID does not exist or is inaccessible.</p><p><strong>Resolution</strong>:</p><ul><li>Ensure the Project ID matches the correct Google Cloud project.</li><li>Confirm the Application ID corresponds to an existing dataset in the project and that the dataset is accessible.</li></ul></td></tr><tr><td>3</td><td>com.google.api.client.auth.oauth2.TokenResponseException: 401 Unauthorized</td><td><p>Authentication failed because the service account key is invalid, expired, or deleted, or because the associated service account is disabled.</p><p><strong>Resolution</strong>:</p><ul><li>Regenerate a new service account key from the GCP Console.</li><li>Confirm the private key entered matches the value in the service account JSON, entered only up to the point before the line break markers.</li><li>Verify the service account is active and has the required BigQuery permissions.</li><li>Replace the old key in the connection configuration.</li></ul></td></tr><tr><td>4</td><td>com.google.api.client.googleapis.json.GoogleJsonResponseException: 403</td><td><p>The service account does not have sufficient IAM roles to query data or run BigQuery jobs.</p><p><strong>Resolution</strong>:</p><p>Grant the required roles to the service account in Google Cloud IAM.</p><p>Minimum recommended roles:</p><ul><li>roles/bigquery.user</li><li>roles/bigquery.dataViewer</li><li>roles/bigquery.jobUser</li></ul></td></tr><tr><td>5</td><td>Error while validating connection: 403 permission exception</td><td><p>The service account being used has not been granted access to the specific project ID being connected to.</p><p>Resolution:</p><ul><li>Confirm the service account has been granted access to the intended project ID.</li><li>Verify the required BigQuery permissions, data viewer, metadata viewer, and job user, have been assigned to the service account for that project.</li><li>Reconfirm access with the relevant GCP administrator if the mismatch continues.</li></ul></td></tr><tr><td>6</td><td>Error while validating connection: invalid details in application or project ID</td><td><p>This historically occurred when the project ID and the application or data set ID entered did not correspond to each other, meaning the data set did not exist within the specified project.</p><p>Resolution:</p><ul><li>Confirm that the project ID and application or data set ID entered belong to the same project.</li><li>Retry validation once the correct project and data set pairing is confirmed.</li></ul></td></tr></tbody></table>
{% endtab %}

{% tab title="Crawling & Profiling" %}

<table data-search="true"><thead><tr><th width="60.140625">S. No</th><th width="200.41796875">Error Message</th><th width="454.9296875">Error Description &#x26; Resolution</th></tr></thead><tbody><tr><td>1</td><td>A project configured with service account access does not appear in the connector after crawling</td><td><p>Access permission changes made to a service account can take some time to reflect, or the project may not currently be listed in the connector's configured project IDs.</p><p><strong>Resolution</strong>:</p><ul><li>Confirm the project ID is included in the connector's configured list, or left blank to include all accessible projects.</li><li>Allow some time for recently updated service account permissions to take effect before retrying.</li><li>Recrawl the connector once access has been confirmed as active.</li></ul></td></tr><tr><td>2</td><td>Profile completed with a data type not supported warning on certain columns</td><td><p>Certain data types do not have a structured format that allows minimum and maximum values to be calculated, so these columns are skipped with a warning rather than an error during profiling.</p><p><strong>Resolution</strong>:</p><ul><li>Confirm the flagged column uses one of the currently unsupported data types for profiling.</li><li>Treat this as an expected warning rather than a failure, since these columns are intentionally skipped.</li><li>Refer to the Data Types with Limited Support section for the list of unsupported data types.</li></ul></td></tr><tr><td>3</td><td>Null count, distinct count, or other profile statistics not appearing for a table</td><td><p>These statistics require the data viewer and job user permissions, since they are generated by running a query against the actual data rather than just reading structural metadata.</p><p><strong>Resolution</strong>:</p><ul><li>Confirm the service account has been granted both data viewer and job user permissions.</li><li>Confirm the metadata viewer permission is also present, since this supports the underlying cataloguing needed for profiling.</li><li>Recrawl and reprofile the table once all required permissions are confirmed.</li></ul></td></tr><tr><td>4</td><td>Query in the query sheet exceeds the configured time limit</td><td><p>The query being run is taking longer than the currently configured query timeout setting.</p><p><strong>Resolution</strong>:</p><ul><li>Increase the query timeout value in the connector settings if longer-running queries are expected.</li><li>Review the query for potential performance issues if it is taking unusually long to complete.</li><li>Retry the query once the timeout has been adjusted appropriately.</li></ul></td></tr></tbody></table>
{% endtab %}
{% endtabs %}

## FAQs

{% tabs %}
{% tab title="General" %}

<table data-search="true"><thead><tr><th width="59.91015625">S. No</th><th width="201.46875">Question</th><th>Answer</th></tr></thead><tbody><tr><td>1</td><td>What is BigQuery, and how does its structure map to the application's catalog?</td><td><p>BigQuery is a fully managed, cloud-based data warehouse service within the Google Cloud Platform. Google manages the underlying database infrastructure and physical maintenance.</p><p>In the application's catalog:</p><ul><li>Google Cloud project → Database</li><li>Data set (application ID) → Schema</li><li>Tables, columns, views, and procedures → Objects under the schema</li></ul><p>The standard naming format is project ID followed by data set ID.</p></td></tr><tr><td>2</td><td>Why is BigQuery categorized as an RDBMS type connector even though it is a data warehouse product?</td><td><p>Although BigQuery is a cloud data warehouse, it stores data in a structured format with tables, columns, views, and procedures, similar to a traditional relational database.</p><p>Therefore, it is catalogued and represented as an RDBMS type connector.</p></td></tr><tr><td>3</td><td>What connectivity methods does this connector use behind the scenes?</td><td><p>The connector uses two connectivity methods:</p><ul><li>JDBC</li><li>SDK</li></ul><p>There is no separate option to select the method during setup. The connector automatically uses the appropriate method as required.</p><p>No additional driver file is required because the necessary components are already bundled with the connector.</p></td></tr></tbody></table>
{% endtab %}

{% tab title="Authentication" %}

<table data-search="true"><thead><tr><th width="59.23046875">S. No</th><th width="201.41015625">Question</th><th>Answer</th></tr></thead><tbody><tr><td>1</td><td>What authentication types are available for this connector?</td><td><p>Two authentication types are available:</p><ul><li>File authentication: Uses a service account JSON key file placed in a path accessible to the application or in the bridge client folder when a bridge is used.</li><li>UI authentication: Allows the same service account credentials, including the private key, to be entered directly in the connection fields.</li></ul><p>UI authentication can be used when placing the JSON key file directly on the server is not preferred for security reasons.</p><p>Both authentication types use the same underlying service account credentials.</p></td></tr><tr><td>2</td><td>What permissions are required on the service account?</td><td><p>The following permissions are generally required:</p><ul><li>BigQuery data viewer: Required for profiling and viewing data in the data tab.</li><li>BigQuery metadata viewer: Required for crawling and cataloguing.</li><li>BigQuery job user: Required for operations that submit a query job within BigQuery, such as retrieving table or column details.</li></ul></td></tr><tr><td>3</td><td>Are the project ID and application or data set ID fields mandatory?</td><td><p>No. As of the current version, these fields are not mandatory.</p><ul><li>Multiple project IDs can be entered, separated by commas, to retrieve data sets from specific projects.</li><li>The fields can also be left blank to retrieve all projects and data sets accessible to the configured service account.</li></ul></td></tr><tr><td>4</td><td>How does the private key need to be entered when using UI authentication?</td><td><p>For UI authentication, enter only the required portion of the private key up to the point before the line break markers in the original key.</p><p>The complete key text, including those markers, should not be entered.</p><p>This applies only to UI authentication. File authentication does not require manual private key entry.</p></td></tr><tr><td>5</td><td>What is the purpose of the regions field in the connector settings?</td><td><p>The regions field specifies the geographic regions where the BigQuery projects or data sets are located.</p><p>Enter multiple regions separated by commas to ensure that data sets outside the default regions are also picked up during crawling.</p></td></tr><tr><td>6</td><td>What is the billing project ID field used for?</td><td><p>The billing project ID specifies the project under which a query job runs for billing purposes during crawling or profiling.</p><ul><li>If configured, the query job runs under the specified billing project ID.</li><li>If not configured, it uses the standard project associated with the connection.</li></ul></td></tr></tbody></table>
{% endtab %}

{% tab title="Crawling and Profiling" %}

<table data-search="true"><thead><tr><th width="59.23046875">S. No</th><th width="201.41015625">Question</th><th>Answer</th></tr></thead><tbody><tr><td>1</td><td>What object types are catalogued for BigQuery?</td><td><p>The connector catalogues:</p><ul><li>Tables</li><li>Columns</li><li>Views</li><li>Functions</li><li>Triggers</li><li>Procedures</li></ul><p>Indexes and synonyms are not applicable to BigQuery because these concepts do not exist in its architecture in the same way as in traditional relational databases.</p></td></tr><tr><td>2</td><td>Does profiling use full profiling or sample profiling by default?</td><td><p>Full profiling is used by default.</p><p>Sample profiling can be configured through the profile settings when a lighter-weight profiling approach is preferred, particularly for larger tables.</p></td></tr><tr><td>3</td><td>How many records are shown by default in the query sheet?</td><td><p>The query sheet displays 1,000 records by default when a table is selected.</p><p>Additional records can be accessed through pagination when using advanced mode.</p></td></tr><tr><td>4</td><td>Does the query policy setting that shows an authorization popup apply to BigQuery?</td><td><p>This setting is generally more relevant to connectors that use simple username and password authentication.</p><p>BigQuery uses File authentication or UI authentication with service account credentials instead.</p><p>However, query type and role-based restrictions can still be configured to control the operations a user can perform in the query sheet.</p></td></tr><tr><td>5</td><td>Are external tables supported by this connector?</td><td><p>External tables are catalogued but are not supported for profiling.</p><p>Their structural information is available in the catalog, but profiling statistics are not generated.</p></td></tr><tr><td>6</td><td>Is tag-based crawling supported for BigQuery?</td><td><p>No. Tag-based crawling is not currently supported for BigQuery.</p><p>It may be considered as a future enhancement.</p></td></tr></tbody></table>
{% endtab %}
{% endtabs %}

***

Copyright © 2026, OvalEdge LLC, Peachtree Corners, GA, USA.


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.ovaledge.com/release8.3/connectors/connector-repositories/data-warehouse/bigquery.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.
